


Open LLM Leaderboard
What is Open LLM Leaderboard?
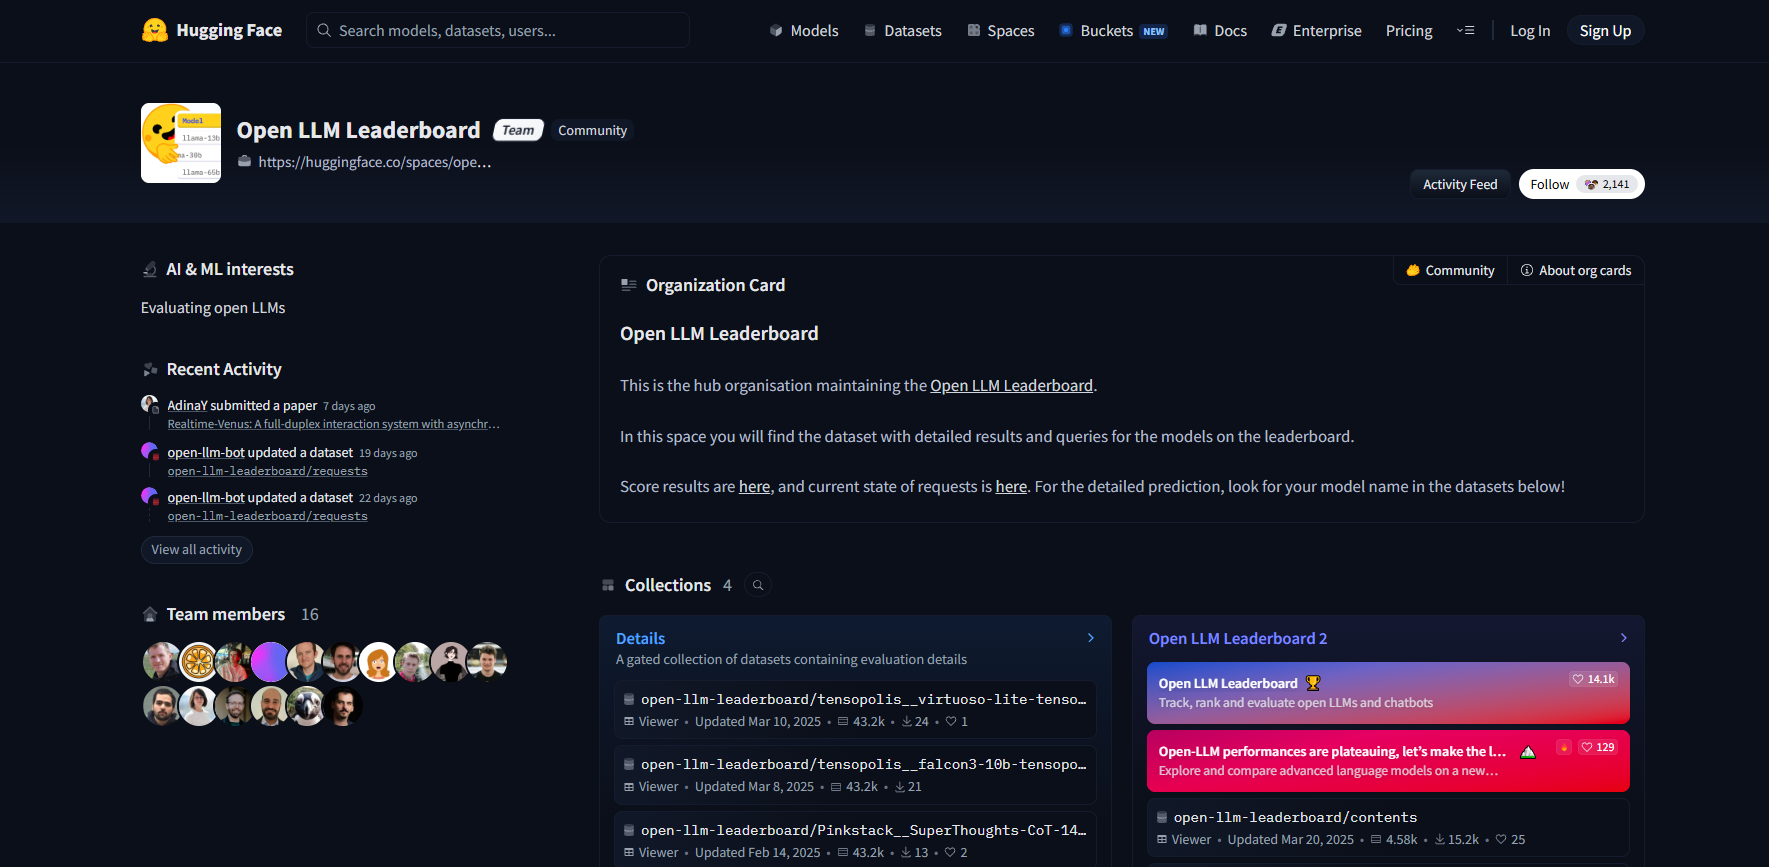
Open LLM Leaderboard is an open-source leaderboard for large models launched by HuggingFace, the largest community for large models and datasets. It’s based on the Eleuther AI Language Model Evaluation Harness framework. Open LLM Leaderboard evaluates models across multiple dimensions, including instruction compliance, complex reasoning, mathematical problem-solving, and knowledge-based question answering, using various benchmarks such as IFEval, BBH, and MATH. The leaderboard covers various models, including pre-trained models and chatbot models, providing detailed numerical results and model input/output details. Open LLM Leaderboard helps users identify the most advanced models and contributes to the advancement of the open-source community.
Main functions of Open LLM Leaderboard
- Multi-dimensional benchmarking : Includes various benchmarks (such as IFEval, BBH, MATH, GPQA, etc.), covering multiple areas such as instruction compliance, complex reasoning, mathematical problem-solving, and professional knowledge question answering, to comprehensively evaluate the model’s capabilities.
- Multiple model types supported : Supports pre-trained models, continuously pre-trained models, domain-specific fine-tuning models, chat models, etc., covering different application scenarios.
- Detailed results display : Provides detailed numerical results and model input and output details to help users gain a deeper understanding of the model’s performance.
- Community interaction : Community members tag and discuss the models to ensure the fairness and transparency of the leaderboard.
- Reproducibility support : Provides code and tools to help users reproduce the results on the leaderboard, enhancing the credibility of the research.
Evaluation Benchmarks for Open LLM Leaderboard
- IFEval : Evaluates the model’s ability to follow explicit instructions, such as format requirements, using strict accuracy metrics.
- BBH (Big Bench Hard): Tests the model’s overall capabilities with 23 challenging sub-tasks covering multi-step arithmetic, algorithmic reasoning, and language understanding.
- MATH : Tests the model’s ability to solve high school competition-level math problems, requiring strict adherence to a specific output format.
- GPQA (Graduate-Level Google-Proof Q&A Benchmark): A challenging knowledge-based question-and-answer task designed by experts, covering professional knowledge from multiple fields.
- MuSR (Multistep Soft Reasoning): Evaluates a model’s long-range context parsing and reasoning ability using complex multistep reasoning problems, such as murder puzzles.
- MMLU-PRO (Massive Multitask Language Understanding – Professional): An improved version of multitask language understanding assessment that increases the number of choices, raises the difficulty of questions, and reduces noise.
Application scenarios of Open LLM Leaderboard
- Model evaluation and selection : Developers and researchers can quickly screen out the optimal open-source language models suitable for specific tasks (such as intelligent customer service, content generation, etc.).
- Academic research : Provide a unified benchmarking platform for the academic community to help researchers evaluate model performance and promote the development of language modeling technology.
- Community interaction : Promote interaction within the open-source community, encourage developers to submit models to leaderboards, and share research results.
- Education and Learning : As an educational resource, it helps students and beginners understand the evaluation methods and performance indicators of language models and provides a platform for practice.
- Technical verification and comparison : Verify whether the newly developed language model meets industry standards, compare it with other models to identify its own advantages and disadvantages, and provide a reference for optimization.
相关导航


