


CMMLU
What is CMMLU?
CMMLU is a comprehensive Chinese language modeling benchmark specifically designed to evaluate the knowledge and reasoning abilities of language models in Chinese contexts. It covers 67 topics ranging from basic disciplines to advanced professional levels. These include natural sciences requiring computation and reasoning, humanities and social sciences requiring knowledge, and Chinese driving rules requiring common sense. Many tasks in CMMLU have China-specific answers that may not be universally applicable in other regions or languages. CMMLU provides abundant test data and leaderboards, supports multiple evaluation methods such as five-shot and zero-shot tests, and is an important tool for measuring the performance of Chinese language models.
Main functions of CMMLU
- Leaderboard : Shows the performance of different language models in five-shot and zero-shot tests, helping to compare model performance.
- Datasets : Provide development and testing data to support rapid use and evaluation.
- Preprocessing code : Provides hint generation methods to facilitate model training and testing.
- Evaluation tools : Supports multiple evaluation methods, making it easy for researchers and developers to test the model’s capabilities.
How to use CMMLU
- Obtain the dataset :
-
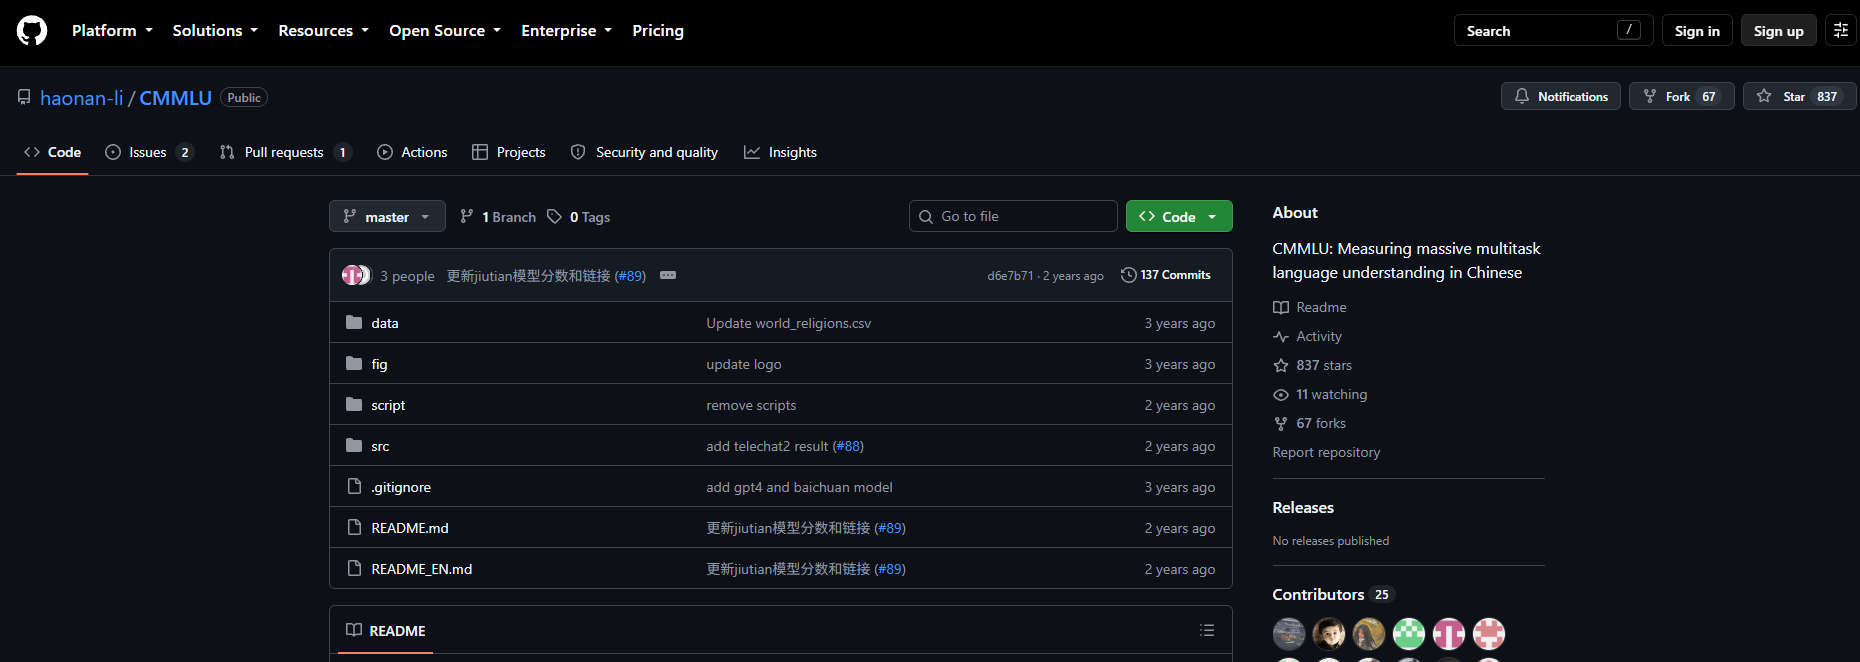
Download from GitHub : Visit the CMMLU GitHub page: https://github.com/haonan-li/CMMLU/,
dataand find the development and test datasets in the directory. -
Obtain it via Hugging Face : Access the Hugging Face platform: https://huggingface.co/datasets/haonan-li/cmmlu, and directly load the CMMLU dataset.
-
- Preparing the test environment :
-
Install dependencies : Ensure that the necessary Python libraries, such as
transformers, are installeddatasets. - Clone the codebase : Clone CMMLU’s GitHub repository to obtain test code and preprocessing tools.
-
相关导航


